The Best Optimizer Depends on Batch Size
Larger batches can speed up training, but often require a different learning rate and other hyperparameters.1 Scaling rules tell us how to adjust these settings without another search. But different theories recommend different rules for the same optimizer.
Q1Can a hyperparameter scaling rule consistently work in different training settings?
Batch size may also change which optimizer works best. Larger batches reduce gradient noise, which can affect optimizers differently. However, standard optimization benchmarks like AlgoPerf and NanoGPT rank optimizers according to experiments run at a fixed batch size. We compare optimizers across batch sizes and carefully retune each one at every batch size.
Q2Do optimizer rankings persist across batch sizes after extensive retuning?
Deriving and testing scaling rules.
We use Muon to test how well these competing scaling rules work across tasks and batch sizes.
Muon optimizer
- Matrix weights
- Minibatch gradient
- Momentum retention
- Learning rate
- Weight decay
- Momentum
- Approximate orthogonalization using Newton–Schulz.
The subscript M denotes the matrix-parameter group.
In these experiments, Muon updates matrix weights and AdamW updates auxiliary parameters.2 The equations below show how each rule adjusts Muon’s hyperparameters when the batch size grows by a factor of . Primes denote their values at the new batch size.
Matching an SDE
Linear learning rate.We adapt an SDE-matching framework for Adam and RMSprop to Muon.3 The derivation holds the gradient–momentum mixing coefficient fixed, but Muon ties it to momentum, so the match is not exact.Minimizing a bound
Square-root learning rate.This approach balances two terms in a theoretical convergence bound: one for initialization and one for loss smoothness.4 The square-root rule applies until the bound’s effective step-size cap is reached.Power Lines
Fixed learning rate.Power Lines keeps AdamW’s nominal parameter-averaging timescale fixed as batch size changes at a fixed token budget.5 We apply the same identity to Muon while holding momentum fixed.We tune this configuration at a reference batch size for language modeling and image classification, then increase the batch size while keeping each task’s training budget fixed. We compare hundreds of scaling rules, including the candidates above and other combinations of learning rate, momentum, and weight-decay adjustments.6
Takeaway: The best scaling rule depends on both the task and target batch size.
Optimizer rankings across batch sizes.
We compare Adam, Lion, Muon, SOAP, and Shampoo in language-model pretraining, retuning each optimizer at every batch size from 128K to 2M tokens. All runs use the same total training budget. We test both weight decay, which shrinks weights, and HyperBall, which keeps each hidden matrix’s norm fixed.
Under HyperBall, Muon outperforms Shampoo at 128K tokens per update, while Shampoo outperforms Muon at 2M.7
Takeaway: The best optimizer at one batch size may lose at another, even after retuning.
Curvature and gradient noise.
We use a quadratic loss with noisy gradients to understand why optimizer rankings can change with batch size.8 We compare SGD with Newton’s method, which divides each direction’s gradient by its curvature.
Noisy quadratic model
- Position in direction
- Curvature in that direction
- Single-example gradient-noise variance
- Batch size
- Learning rate
- Independent standard Gaussian noise, redrawn each step
In our setting, and : the first direction is flat and noisy; the second is sharp and noiseless.
We choose each method’s learning rate to give the lowest average loss after 4,096 samples. Larger batches give us less noisy gradients, but fewer updates.
The map shows which optimizer does better on average. The animation follows one run, so its outcome can differ. Our theorem shows that rankings can reverse even after optimal tuning.9
Takeaway: Newton can reduce bias (remaining initial error) at the cost of higher variance (fluctuations from noisy gradients). Larger batches reduce the variance, which can make Newton beat SGD.
Directional scaling rules.
We study SignSGD on a one-dimensional noisy quadratic, where the sign of momentum determines the update direction.
SignSGD and curvature-to-noise ratio
- Parameter value
- Noisy minibatch gradient
- Momentum average, initialized to zero
- Momentum retention, fixed at 0.9
- Learning rate
- Curvature
- Single-example gradient-noise variance
The sign tells us which way to move, and the learning rate sets the step size. Higher CNR means less noise relative to squared curvature.
In the binoculars below, the valley’s shape represents curvature and blur represents gradient noise. At the same batch size and distance from the minimum, higher CNR makes the downhill direction easier to identify.
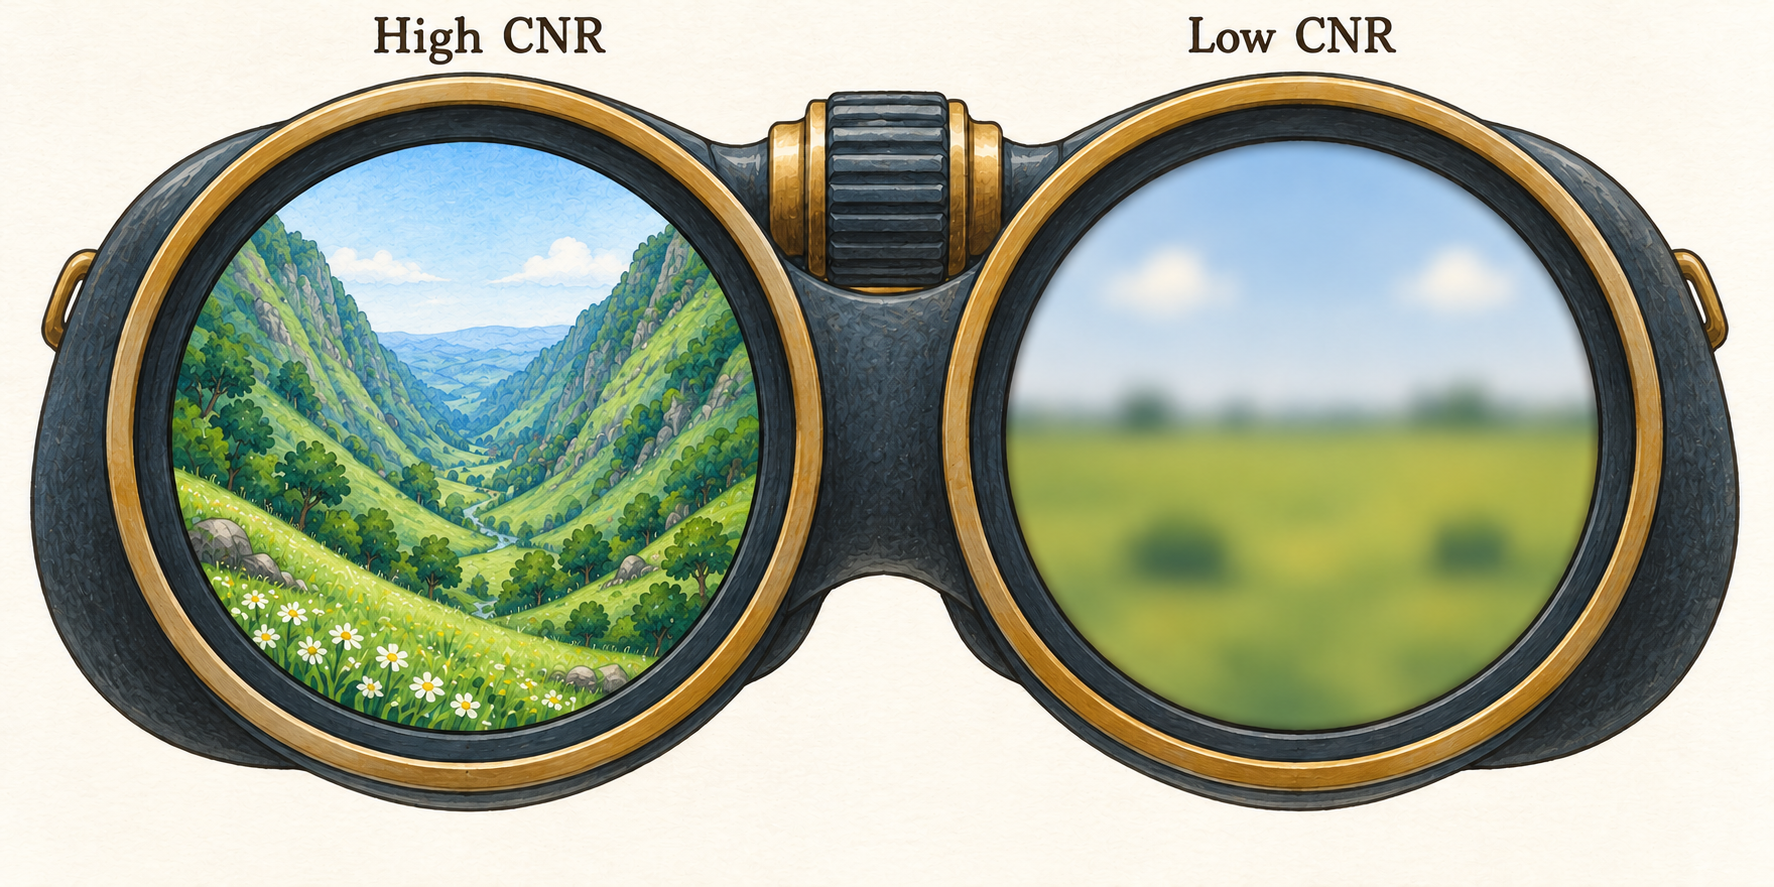
We vary the noise and retune the learning rate at each batch size, keeping other settings fixed. As CNR increases, the tuned rates shift from roughly square-root toward linear scaling.10
Takeaway: Even for the same optimizer, the best scaling rule depends on the landscape and the gradient noise.
Takeaway: One learning rate scaling rule cannot preserve movement in both directions as batch size grows.
The sharp-subspace intervention.
Does a small set of directions account for the cost of increasing batch size in a language model? Building on the previous checkpoint-branching method12, we test different batch sizes in different matrix directions.
We compare a 128K-token control with updates scaled to 2M tokens. In other branches, we keep small-batch updates in the sharpest directions or in a random subspace. We select sharp directions using a local curvature estimate after Muon’s preconditioning. All other parameters keep their original AdamW updates.
Measuring the local batch-size penalty
- Validation loss at the end of a branch
- Loss of the matching 128K control
- Penalty with large-batch updates in every matrix direction
- Penalty with small-batch updates in the selected directions
- Fraction of the fully scaled penalty removed
Branches start from the same checkpoint and use the same training data. Recovery measures a local loss penalty, not savings in total training cost.
Keeping small-batch updates in the sharpest 768 directions, about 0.001% of the matrix-parameter space, removes up to 59.5% of the local penalty. A random subspace of the same size changes it by at most 3%. The benefit largely disappears near the end of training.13
Takeaway: A tiny set of sharp directions can drive much of the local error from increasing batch size.
Takeaways
Batch size can change which optimizer works best, even after retuning. We encourage researchers to design and test optimizers for the batch sizes they will actually be used with. Deriving optimizers and scaling rules that jointly consider gradient noise and the loss landscape is an important direction for future work.